
What Is A/B Testing? A Beginner's Guide to the 6-Step Process, Statistical Significance, and Sample Size
- ab-testing
- cro
- how-to
- beginners
Article summary
- A/B testing is a method where you randomly split visitors, show the original page (A) and a changed page (B) during the same period, and compare which one performs better using numbers
- A simple before-and-after comparison cannot separate the effect of your change from the effects of seasons, ads, days of the week, and so on. Running both versions at the same time is the heart of A/B testing
- The process has 6 steps: goal and metric → hypothesis → create the variation → run → judge → apply. Decide the required sample size (amount of data) and duration before you start
- "Statistical significance" is a guideline for whether a difference is hard to explain by random variation alone. A p-value is not "the probability that B is winning"
- Most failures come from "checking results over and over and stopping early," "changing too many things at once," and "running the test for too short a time"
- On low-traffic sites, you can still get more to go on by changing your approach, such as focusing on bigger changes or looking at an earlier-stage metric
"Maybe changing the headline would get more sign-ups." "Shouldn't the button be higher up the page?" When you run a website, ideas for improvement keep coming. But whether a change will actually make things better or worse is something you can't know until you try. And even if your numbers go up after a change, it is often impossible to tell whether the change deserves the credit or whether you simply happened to increase ad spend that week.
When you want to confirm the effect of a change separately from other factors, you use an A/B test.
This article walks through what A/B testing means and how it works, then covers the practical steps, how to write a hypothesis, how much data and time you need, what "significant difference" actually means, and the mistakes beginners most often make. Some statistics come up, but I keep formulas to a minimum and put understanding the ideas first. All calculation examples in this article use hypothetical numbers chosen for illustration.
What Is A/B Testing?
A/B testing is a method where you randomly show visitors one of two versions of a page and compare which one produces better results, using data from the same period. It is sometimes called "split testing."
- A (control / the original version): the current page. It is the baseline for comparison
- B (variant / the changed version): a page with part of it changed. It is the idea you want to try
For example, you show version A to half of your visitors and version B to the other half, then compare the share of each group that completed a sign-up. This share is called the conversion rate (CVR). A conversion is an action you want visitors to take on your site, such as a purchase, a sign-up, or a request for materials.
The name "A/B testing" comes from comparing two versions, but you can also compare three or more at once (this is called A/B/n testing). The idea is the same.
How it works: split randomly and compare at the same time
Three mechanisms make an A/B test work.
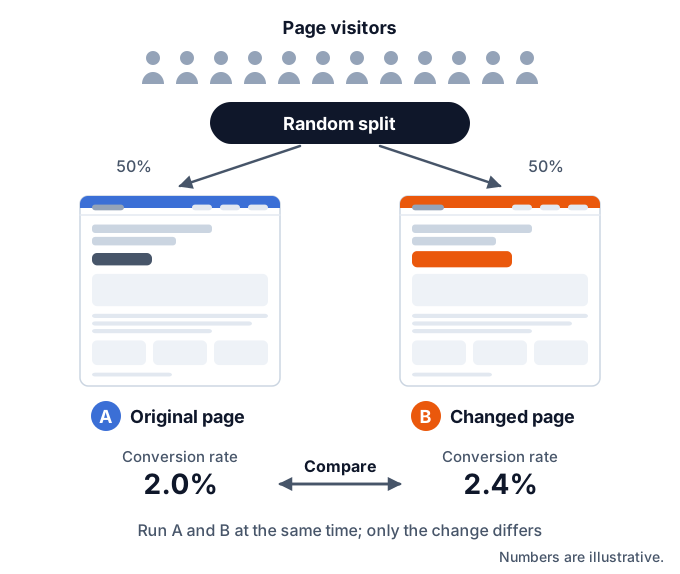
1. Visitors are assigned at random. Whether a visitor sees A or B is decided by the tool using random numbers. A person doesn't choose, and the split doesn't follow a rule such as "A in the morning, B in the afternoon." Random assignment means that differences between visitors, such as new versus returning, smartphone versus desktop, or people from ads versus people from search, end up mixed in roughly equal proportions in both A and B.
2. Both versions run during the same period. A and B are served at the same time. So outside influences such as sales, seasons, a TV mention, or day-of-week swings affect A and B in the same way.
3. The same person keeps seeing the same version. If someone assigned to B sees A on their next visit, you can no longer tell which version influenced their sign-up. For this reason, most tools use a marker stored in the browser (such as a cookie) to keep showing the same version to the same visitor.
When these three conditions are met, the only difference between A and B is "what you changed on the page." That is why, when the results differ, it is easier to attribute the difference to the change. It is the same idea as the randomized controlled trials used to test the effects of medicines, applied to websites.
Why You Need A/B Testing: What Before-and-After Comparisons Can't Tell You
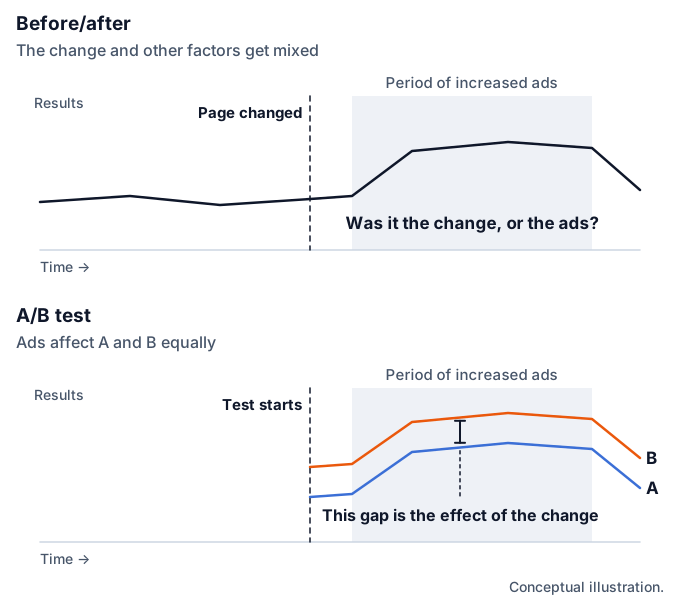
You might wonder, "Why not just change the page and compare the numbers before and after, without splitting visitors?" This is called a before-and-after comparison. It is easy, but it has a big weakness: you cannot separate the effect of your change from other factors.
Your site's numbers move day to day even if you change nothing on the page. Factors that move them include:
- Seasons and events: bonus season, fiscal year-end, holidays, weather, and so on
- Ads and campaigns: increases or decreases in ad spend, changes in ad destinations, email newsletter sends
- Day of week and time of day: weekday and weekend visitors can differ in type and purpose
- Changes in traffic sources: shifts in search rankings, going viral on social media, referrals from other sites
- Competitors and the market: a competitor's price cut, news coverage
In a before-and-after comparison, if any of these overlap with the period after your change, you can't tell whether a change in the numbers comes from your change or from something else. Even if the numbers rose after the change, it is possible that the change itself actually hurt and an increase in ads was hiding that.
An A/B test serves A and B during the same period, so these factors affect both equally. You then look at the remaining difference, which makes it easier to isolate the effect of the change alone.
Another reason is that the builder's intuition and visitors' reactions often don't match. It is not unusual for an idea that everyone internally agreed was "easier to understand" to fall flat with real visitors. A/B testing is also a way to decide based on what visitors actually do, not on who argues loudest or who has the senior title.
What A/B Testing Can and Can't Tell You
A/B testing is powerful, but it can't tell you everything. Knowing what it is good and bad at before you start helps you avoid misreading the results.
What it can tell you
- Whether a change raised, lowered, or barely changed the metric you chose (such as sign-up rate)
- Whether the difference is large enough that random variation alone has trouble explaining it
What it can't tell you, or isn't good at
- Why there was a difference: the reason is a guess. Consider it together with other data
- Long-term effects: it only sees behavior during the test period. It often can't tell you about retention or cancellation rates months later
- Comparisons with ideas you didn't test: you learn which of A and B is better, but not whether a better option C exists
- Small improvements on low-traffic pages: there may not be enough data to tell either way, whether or not a difference exists (the section below on this covers what to do)
Also, A/B testing is "a tool for checking ideas," not "a tool for coming up with good ideas." The quality of the ideas you test is determined by how you build your hypotheses.
Types of A/B Tests: How They Differ from Multivariate and Redirect Tests
Even within "A/B testing," there are several related methods. Here are the ones that come up most often.
| Type | What it compares | Best suited for | Watch out for |
|---|---|---|---|
| A/B test | Versions at the same URL with one part changed | Checking the effect of a single change, such as a headline, button, or image | The basic form. Start here |
| A/B/n test | Three or more versions | You have several headline candidates and want to compare them at once | The more versions, the less data per version and the longer the test |
| Multivariate test | Combinations of multiple elements (e.g., 2 headlines × 2 images = 4 combinations) | You want to know which combination of elements works best | You need data for every combination. Suited to high-traffic pages |
| Redirect test (split URL test) | Pages with different designs built at separate URLs | You want to compare a new page with a substantially different layout against the current page | The redirect can slightly delay display. You need to consider search engines |
| A/A test | Two identical versions | You want to check whether the tool's traffic splitting and measurement work correctly | A test for inspection, not for improvement |
A multivariate test changes multiple elements at once and compares results for each combination. It can even show how well elements work together, such as "this headline combined with this image works best." However, 3 headlines, 3 images, and 2 buttons make 18 combinations, and each one needs enough data. For sites with limited traffic, running A/B tests one after another is more realistic.
A redirect test sends some visitors to a different URL and compares the results; it is also called a split URL test. It suits large changes, such as rebuilding the structure of the page itself. A regular A/B test, which rewrites elements at the same URL, suits quickly trying small changes like wording or color.
Outside the web, sending two versions of an email subject line or an ad creative and comparing the responses is also called A/B testing. This article covers A/B testing of web pages.
What to Test in an A/B Test
There are many elements you can test. Here are the typical ones.
- Headline (main copy): change from describing features to describing the result the visitor gets. The aim is to convey "this is relevant to me" in the first few seconds
- CTA (call-to-action button): change the wording, position, size, or color. The aim is to make the next action clear
- Main image or video: compare a photo of the product alone with a photo of it in use. The aim is to convey value intuitively
- Forms: reduce the number of fields, split into steps, add example input. The aim is to reduce effort and hesitation
- How prices are shown: how monthly and annual prices are laid out, the order of plans, where tax-included pricing appears. The aim is to make comparing and deciding easier
- Trust-building information: customer track record, testimonials, placement of guarantee and support information. The aim is to reduce anxiety before signing up
- Layout and information order: move key information higher, shorten a long page. The aim is to help visitors reach the information they need sooner
- Navigation: change the number of menu items or their wording. The aim is to reduce confusion and guide visitors to the page they want
CTA stands for "Call To Action." It refers to a button or link that prompts visitors to act, such as "Sign up" or "Request materials."
As a rule, decide where to start by closeness to the result and how much it is seen. Places that connect directly to results, such as sign-up buttons and forms, and the top of the page that many visitors see, are where changes are most likely to show an effect. On the other hand, a small change near the bottom of a page that most people never reach takes a long time to detect even if it works.
"Button color" is often cited as an A/B testing example, but a change in color alone does not necessarily produce a big difference. What matters more than the color itself is whether the problem is that the button blends into its surroundings and goes unnoticed. What to change should be worked backward from the hypothesis, which is covered next.
How to Run an A/B Test [6 Steps]
An A/B test proceeds in the following 6 steps. What matters is to decide the metric, the required amount of data, the duration, and the criteria for judging before you start running it.
Set the goal and metric
Narrow down what you want to improve to one thing, and decide the metric that measures it. Phrase it in a way that can be measured with numbers, such as "raise the completion rate for requesting materials." Use only one metric for judging (the primary metric).
Form a hypothesis
Write down "where the problem is, what you will change and how, and why you think it will improve things." Basing it on data such as web analytics and heatmaps reduces guesswork.
Create the variation to test
Based on the hypothesis, create the changed version (B). To be able to tell what worked, limit the changes to what one hypothesis covers. Check how it displays on both smartphones and desktops.
Decide the required data and duration, then run
Estimate the required sample size and the test duration, decide the traffic allocation, and then start. Right after starting, check that traffic splitting and measurement are working correctly.
Judge after the period ends
Look at the results only after you reach the duration and data volume you decided in advance. Check the difference in the primary metric and whether that difference is within what random variation could explain.
Apply the result and move on to the next hypothesis
Officially adopt the version that did better and clean up the test settings. Even if there was no difference, record what you learned and use it for the next hypothesis.
The following sections explain the thinking behind each step in more detail.
How to Choose Your Goal and Metrics
It helps to organize metrics by their role.
- Primary metric: the metric that decides who wins the test. Choose only one. Examples include purchase completion rate, materials-request completion rate, and free sign-up rate
- Secondary metrics: metrics you look at to understand how the primary metric moved. Examples are button click rate, form start rate, and scroll depth
- Guardrail metrics: metrics you watch to make sure nothing got worse. Examples are bounce rate, page load speed, returns or cancellations, and number of inquiries
The reason to limit yourself to one primary metric is that if you line up many metrics and call it a success when any one of them improves, you are likely to pick up a metric that looked better purely by chance. This is the "multiple comparisons" problem, which comes up again in a later section.
Choose a primary metric that is as close to business results as possible. It can happen that the button click rate rises but sign-ups do not. Wording that invites clicks gets more people to press the button, but if what comes next doesn't match their expectations, they leave.
On the other hand, metrics with few occurrences, such as purchases or contracts, take longer to collect enough data. For sites with limited traffic, one option is to make an earlier-stage metric (such as reaching the form) the primary metric. In that case, it is important to remember the premise that "even if the earlier metric improves, the final result won't necessarily improve."
How to Write a Hypothesis: Turn Behavior Data into a Reason to Change
The success of an A/B test depends heavily on the quality of the hypothesis. If you keep trying ideas without a hypothesis, you end up with a string of tests that show no difference, and even when there is one, you can't build on it.
Writing the hypothesis in the following form reduces gaps.
"From (a fact seen in the data), we think (a guess about the problem). So if we (make this change), (this metric) should improve."
As an example, suppose the following situation (hypothetical).
- Fact: on the pricing page, few visitors scroll far enough to reach the sign-up button
- Guess about the problem: the button is too far down, so even visitors who want to sign up can't find it
- Change: also place a sign-up button right below the plan table
- Metric: sign-up completion rate
Writing it this way lets you look back after the results come in and ask whether "the guess was wrong, or the change wasn't enough."
Data that can feed a hypothesis includes the following.
- Web analytics: which pages have a lot of drop-off, which traffic sources have low results. Good for finding which "page" has a problem
- Heatmaps: how far down the page people read, where they click, whether they click on things that aren't links. Good for finding which "place" has a problem
- Inquiries and sales or support records: what visitors are confused about and worried about
- Surveys and interviews with users: clues to reasons that don't show up in numbers
A heatmap is a tool that overlays visitor behavior on the page as areas of lighter and darker color (see What Is a Heatmap? for types and how to read them). It helps you find problem spots within a page, such as "an important button isn't being clicked" or "many people stop reading partway down." For the division of roles, where you find problems with a heatmap and check the fix with an A/B test, see Heatmaps vs. A/B Testing: Differences and How to Use Each.
When you have multiple hypotheses, rank them on three points: "expected size of impact," "strength of the evidence," and "effort to implement." Starting with those that have high expected impact and low effort makes things easier to move forward.
Understanding Sample Size
Sample size is the amount of data needed for the test, that is, the number of visitors who saw each version. In an A/B test, you estimate this before running it. If the data is too small, you will more often fail to find a difference that really exists, and even when a significant difference happens to appear, its size tends to look larger than it really is.
The required sample size is determined mainly by these four things.
- Current conversion rate: the lower it is, the more data you need
- Size of the difference you want to detect: the smaller the difference you want to find, the more data you need. The smallest difference you want to be able to detect, where you're fine missing anything smaller, is called the minimum detectable effect (MDE)
- Significance level: how much of the error of declaring "there is a difference" when there isn't one you are willing to accept. 5% is commonly used
- Statistical power: the probability of finding a difference when one really exists. 80% is commonly used
Of these, the second has the biggest impact. When the difference you want to find is cut in half, the required amount of data increases about 4 times.
Here is a calculation example to give you a rough idea. These are approximate numbers of visitors needed per variation, assuming a current conversion rate of 2.0% (calculated with a standard formula for comparing two proportions, using a two-sided test, a 5% significance level, and 80% power).
| Improvement you want to detect (relative) | Conversion rate after the change | Visitors needed per variation (approx.) |
|---|---|---|
| +10% | 2.0% → 2.2% | about 80,700 |
| +20% | 2.0% → 2.4% | about 21,100 |
| +30% | 2.0% → 2.6% | about 9,800 |
| +50% | 2.0% → 3.0% | about 3,800 |
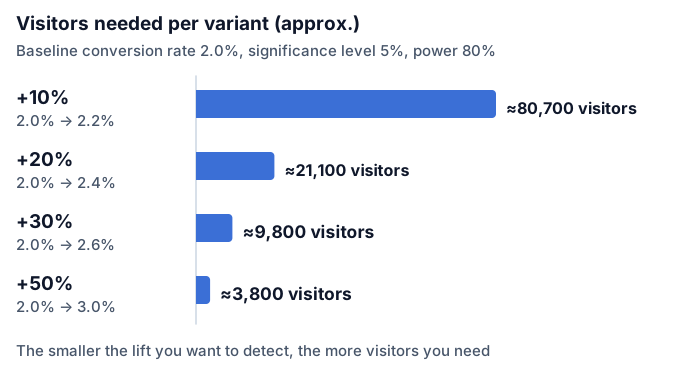
This table shows two things. First, confirming a small improvement takes more data than you might expect. To confirm a 10% improvement on a page with a 2.0% conversion rate, you would need more than 160,000 visitors across A and B combined. Second, the larger the improvement a change aims for, the less data you need to judge it.
When you actually estimate, the calculators built into A/B testing tools or publicly available sample size calculators let you get the answer just by entering the four values. You don't need to memorize the formula. What matters is to first decide "how big a difference do I want to find," and then check whether your site's traffic can get you there in a realistic amount of time.
If the required number you estimate is too large, there are options other than giving up on testing: focus on a change likely to produce a bigger difference, run the test on a high-traffic page, or look at a metric earlier in the funnel. The section on "What to do on a low-traffic site" explains how.
How to Decide the Test Duration
Estimate the test duration by dividing the required sample size by the number of people who visit the tested page per day.
Here is an example. Suppose the table above says you need "about 21,100 per variation." Say the target page gets 1,000 visitors a day, and assume everyone is included in the test and split half and half between A and B, so each variation gets 500 a day. 21,100 ÷ 500 comes to about 42 days, or about 6 weeks.
When deciding the duration, consider the following points in addition to the amount of data.
Use whole weeks. Visitor behavior changes by day of week. Weekdays may be work-related research and weekends personal shopping, so the type and purpose of visitors can differ. If you finish after just four days, Monday through Thursday, the reactions of weekend visitors are missing. Starting and ending on the same day of the week, in multiples of 7 days, avoids day-of-week bias.
Avoid too short a period. Even on very high-traffic sites that reach the required number in a few days, a common rule of thumb is to run for at least 1 week, ideally 2 weeks. In addition to day-of-week bias, reactions can be better right after a change just because it is new (or worse because returning visitors are thrown off).
Avoid too long a period, too. The longer a test runs, the more disturbances creep in, such as cookies being deleted so the same person sees a different version, or seasons and market conditions changing. If your estimate comes out well over 2 months, we recommend revisiting the design of the test (the size of the difference you want to detect, the target page, and the metric).
Avoid unusual periods. Results from periods when visitor behavior is very different from usual, such as big sales or the year-end holidays, may not apply to normal periods. Unless you want to check a measure specific to that period, it is safer to avoid them.
What Is Statistical Significance? A Plain Explanation of p-Values and Confidence Levels
When the test ends, you get a result like "A is 2.0%, B is 2.4%." What you need to think about here is whether this difference is real or just chance.
Even if you show exactly the same page to two groups, their conversion rates will almost never match exactly. Just as flipping a coin 100 times doesn't always give exactly 50 heads, numbers have random variation. So you need a procedure to check "whether the observed difference is within what random variation alone could explain." This is statistical hypothesis testing, and the term for its conclusion is statistical significance.
What is a p-value?
In a test, you first assume that "there is truly no difference between A and B." Then you calculate the probability of seeing a difference at least as large as the one observed, by chance, if there were truly no difference. This probability is the p-value.
- A small p-value → under the assumption of no difference, a difference like this would rarely occur → the assumption of no difference looks doubtful
- A large p-value → a difference this size shows up often by chance even when there is no difference → you can't say there is a difference
Significance level and confidence level
The threshold for how small the p-value must be before you conclude "there is a difference" is called the significance level. By convention, 5% (0.05) is commonly used. When the p-value falls below the significance level, we say "there is a statistically significant difference."
On A/B testing tool screens, you often see displays such as "95% confidence level" or "95% confidence." This usually means the tool is judging at a 5% significance level (the meaning of the display varies by tool, so check your tool's documentation).
A 5% significance level is an agreement that "we accept up to a 5% chance of declaring a difference when there really isn't one." Put another way, if you test 20 changes that have no effect at all, on average 1 of them will show up as "significant." A significant difference is not proof of certainty; it is a guideline for keeping the chance of error below a set level.
Common misunderstandings about p-values
Other common misunderstandings include the following.
- "Not significant" does not mean "there is no difference": it includes the situation where there isn't enough data to say whether a difference exists
- A significant difference is not necessarily a meaningful size for your business: with a very large amount of data, even a tiny difference becomes significant. Look at the size of the difference as well
- A smaller p-value does not mean a larger effect: the p-value also depends on the amount of data
Checking with calculation examples
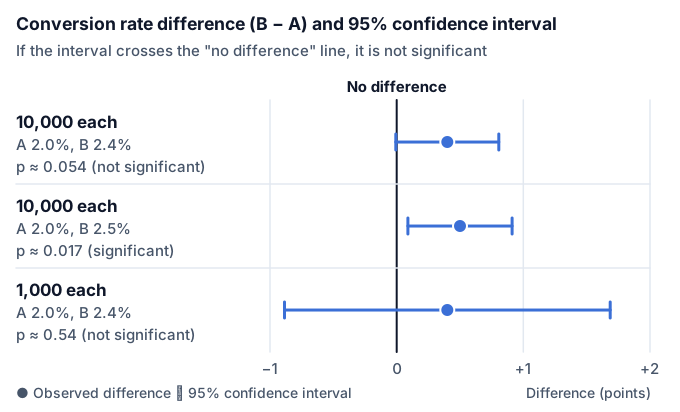
Let's check with hypothetical numbers. Suppose 10,000 visitors are assigned to each of A and B.
- Example 1: A has 200 conversions (2.0%) and B has 240 (2.4%). The p-value is about 0.054, just above the 5% significance level. Even though a 20% relative difference is visible, you can't call it "significant" with this amount of data
- Example 2: A has 200 conversions (2.0%) and B has 250 (2.5%). The p-value is about 0.017, below the 5% significance level
With the same rates, the conclusion changes if there is less data. If A and B each had 1,000 visitors, with 20 conversions (2.0%) for A and 24 (2.4%) for B, the p-value is about 0.54. That means that even with no difference, a gap this size shows up by chance more than half the time.
(All of these are examples calculated with a two-sided test for the difference between two proportions. For actual judgments, follow the method your tool uses.)
Look at the confidence interval, too
A p-value tends to turn into a yes-or-no question of "significant or not," but looking at the confidence interval gives you a sense of the size of the difference. A confidence interval is a range within which the true difference is considered likely to fall.
In Example 1 above, the difference in conversion rate (B minus A) is 0.4 percentage points, and the 95% confidence interval works out to roughly −0.01 to +0.81 percentage points. Because the interval just barely crosses zero, you can read it as "B looks better, but we can't rule out that there is no difference." A wide interval is a sign that you don't have enough data yet.
Some tools show "probability that B beats A"
Some tools show a number like "the probability that B beats A" instead of a p-value. This value is based on a different approach called Bayesian statistics, and its assumptions and meaning differ from those of a p-value. Neither is simply right or wrong; they are different schools of thought. What matters is to check which method the number you are looking at uses and not to confuse the two as the same kind of number.
How to Read the Results and What to Do After the Test
Once the period ends, check the results in this order.
- Whether the traffic split went as designed: if you set a half-and-half split, are the visitor counts for A and B badly lopsided? If the imbalance is large, there may be a problem with the splitting or measurement, and it is dangerous to trust the results as they are
- The difference in the primary metric and its significance: the direction of the difference, its size, the p-value and confidence interval
- Guardrail metrics: while the primary metric improved, did other important numbers get worse?
- Secondary metrics: clues for thinking about why you got this result
The results fall into three broad cases.
B was significantly better. Officially adopt B. Keep watching the numbers for a while after applying it to confirm the same trend continues as during the test.
B was significantly worse. Stay with A. This is not a failure; the result is that you stopped a bad change before showing it to everyone. Thinking about why it was worse will improve the accuracy of your next hypothesis.
There was no significant difference. In A/B testing, this is one of the most common outcomes. In this case, avoid "extending the test until it becomes significant" after the planned period ends (the next section explains why). When there's no difference, separate out whether the hypothesis was wrong, the change was too small, or the data was insufficient. If the results are the same either way, it is fine to choose whichever is easier to operate or fits your brand guidelines.
Looking at results broken down by device or traffic source (segment analysis) is also useful, but it calls for caution. The finer you slice, the less data each group has, and the more easily you pick up chance differences. It is safer to treat trends found by slicing as "hypotheses to check next," not as "conclusions."
Finally, keep a record of the test. Putting the hypothesis, changes, duration, amount of data, results, and takeaways in one place prevents repeating the same test and passes on what you learned even when the person in charge changes.
Common A/B Testing Mistakes and How to Avoid Them
Because the mechanism of A/B testing is simple, going about it the wrong way can produce a wrong conclusion that comes with plausible-looking numbers. Here are the typical mistakes.
| Common mistake | What the problem is | Fix |
|---|---|---|
| Checking results repeatedly and stopping as soon as they turn significant | The error of calling a chance difference "significant" becomes more frequent than the significance level you set | Decide the required data and duration in advance, and judge after you reach them |
| Changing many elements at once | Even if there is a difference, you can't tell what worked | Limit changes to what one hypothesis covers |
| A short test period | Results are swayed by day-of-week bias and temporary reactions right after the change | Run in multiples of 7 days, at least 1 to 2 weeks |
| Judging with low traffic | Random variation is large and conclusions are unstable | Estimate the required number in advance, and rethink the design if it isn't enough |
| Day-of-week or seasonal bias | Results from weekdays only or a sale period only don't apply to normal times | Start and end on the same day of the week and avoid unusual periods |
| Lining up many metrics and many variations, then picking only the good one | The more comparisons you make, the more likely something looks good by chance | Decide on one primary metric and limit the number of variations |
| Testing without a hypothesis | Even with results, no learning remains to build on | Write out the fact, problem, change, and metric before you begin |
| Changing settings or variations midway | The nature of the data changes before and after, so they can't be compared | If you want to change something, stop and start over as a new test |
The one to be especially careful about is the first, the "peeking" problem. Checking the interim progress of a test almost every day is itself necessary for catching problems early. The problem is stopping the test and declaring a win the moment the interim results show a significant difference.
A p-value swings up and down as data accumulates. Even when there is truly no difference, if you check many times, at some point it may happen to fall below the significance level by chance. If you stop at that moment, the "error of declaring a difference when there is none" becomes more frequent than the 5% you planned for. The rule of waiting to judge until you reach the data volume and duration you decided on in advance exists to prevent this error.
Some tools also have a judging method designed so that errors do not increase even if you judge midway (such as what is called sequential testing). In that case, follow the procedure the tool gives you.
A note on "changing many things at once," too. Even if a B that changes the headline, image, and button all at once wins, you won't know which one worked. It's possible that the headline was good but the image dragged it down. However, if your goal is to compare a completely rebuilt page against the current one, changing things together makes sense. In that case, accept that "you won't know which element worked," and compare them with something like a redirect test.
How to Think About Traffic Allocation and the A/B Split
Two "percentage" settings appear when you configure an A/B test. They are easy to confuse, so understand them separately.
- Traffic allocation (the share of visitors included in the experiment): what percentage of all visitors are included in the test. Visitors outside the test simply see the original page
- A/B split: in what ratio the visitors included in the test are divided between A and B
For example, if you set the traffic allocation to 20% and the A/B split to half and half, 80% of all visitors are outside the test and see the original page, 10% are in the test and see A, and 10% see B.
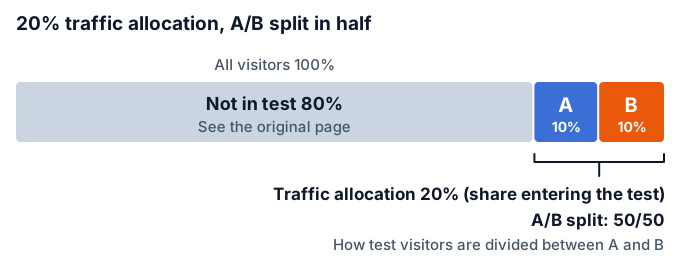
A half-and-half A/B split is the default. With the same number of visitors, splitting evenly collects the required data fastest. You can also give B a smaller share, but you have to wait until the smaller side collects enough data, so the duration gets longer.
Choose the traffic allocation by balancing risk and duration. Lowering the traffic allocation reduces the number of visitors affected if the change backfires. In exchange, fewer visitors are in the test, so it takes longer to collect the data you need. A common approach is to start a large change with unpredictable impact at a low traffic allocation, confirm there are no problems, and widen it if all is well. For a change with little impact, such as swapping some wording, it is more sensible to include everyone from the start and shorten the duration.
The difference between the two percentages is explained in Traffic Allocation vs. A/B Split in A/B Testing, and the design thinking is covered in Why Traffic Allocation and A/B Split Should Be Separate Settings.
A/B Testing and SEO: Limiting the Impact on Search
A common worry is whether "A/B testing will hurt my search rankings." Google publishes guidance on how to run tests while limiting the impact on search, in the Google Search Central documentation. The key points are as follows.
- Don't cloak: intentionally showing different content to search engine crawlers (programs that visit and read pages) and to human visitors is called cloaking, and it violates spam policies. This is true whether or not a test is running. Avoid any setup that shows a particular version only to crawlers
- Use rel="canonical" for tests on separate URLs: when testing across multiple URLs, as in a redirect test, add rel="canonical" (a tag that tells search engines the preferred URL) to the test URLs to indicate that the original URL is the page to prioritize. For this purpose, Google recommends rel="canonical" over noindex
- Use temporary redirects (302) for redirecting: when redirecting from the original URL to a test URL, use 302, which signals a temporary redirect, rather than 301, which signals a permanent one. A JavaScript redirect is also said to be fine
- Run the test only as long as needed: once you have collected enough data, end the test and remove the test URLs, scripts, and so on as soon as you can. Google explains that running a test longer than necessary may be interpreted as an attempt to deceive search engines
In other words, not leaving tests running is important not only for statistics but also for search. Finish the whole flow: clean up tests that are done, and apply the version you adopted to the site itself.
Note that what is introduced here is an overview of the guidance Google has published. The effect on search rankings varies by site, so before running a test that involves a big change, we recommend checking the original document and your tool's documentation as well.
What to Do on a Low-Traffic Site
As we saw in the sample size section, A/B testing needs a fair amount of data. So is A/B testing meaningless for sites with a few thousand monthly visitors? Not necessarily. Changing your approach can give you more to go on.
Test big changes. The larger the difference you want to find, the less data you need. Rather than small changes like tweaking button wording, focus on changes that can produce a big difference: changing the core appeal, reorganizing the structure of the page, or cutting form fields drastically.
Run tests on high-traffic pages. Even if the site as a whole has little traffic, there should be pages where visitors concentrate. Choose the places with the most visitors, such as the home page or pages that receive ad traffic.
Use an earlier-stage metric. Purchases and contracts are few, so detecting a difference takes time. Making a more frequent earlier action the primary metric, such as "reaching the form" or "going to the pricing page," keeps the required data down. Just keep in mind that an improvement in an earlier metric doesn't necessarily lead to improvement in the final result.
Limit yourself to two variations. Adding a third and fourth reduces the data per variation. While traffic is low, compare only A and B.
Set the traffic allocation to 100% and the A/B split to half and half. Narrowing the audience or using an uneven split lengthens the duration.
Allow a longer period, and accept limits if that still isn't enough. If you can't reach the required number even after allowing about 4 to 8 weeks, you also need to decide not to insist on settling it with an A/B test.
When A/B testing isn't a good fit, other methods can help.
- Observe behavior with heatmaps: even with little traffic, you can get a sense of "where people aren't reading" and "where they aren't clicking"
- Ask users directly: simply having a few people use the screen while you watch where they get stuck turns up many problems
- Fix obvious problems without testing: broken links, hard-to-read text, buttons that don't work, and the like, where it's hard to imagine fixing them making things worse, don't need to wait for verification
Types of A/B Testing Tools and How to Choose One
To run A/B tests, you need a tool that handles traffic splitting, switching what's displayed, measurement, and reporting. In terms of how they work, there are two broad types.
Client-side
- How it works: you add a tag (a short snippet of code for measurement) to the page, and part of the page is rewritten in the visitor's browser
- Mainly handled by: marketers and web staff. Many tools let you create changes through on-screen operations
- Suited to: visual changes such as wording, images, colors, and layout
- Watch out for: a "flicker" can occur, where the original display is visible for a moment before the rewrite
Server-side
- How it works: server-side code switches what is shown to each visitor
- Mainly handled by: engineers. Code changes are required
- Suited to: changes that involve back-end processing, such as price calculation, how search or ordering works, and app features
- Watch out for: setup and operation take development effort
For the use this article assumes, trying headlines and buttons on web pages, client-side tools are the first candidates.
When choosing a tool, check the following points.
- Whether you can create changes through on-screen operations or need to write code
- Which statistical method it uses for judging and how it displays results
- Whether you can set traffic allocation and the A/B split separately
- Whether it supports redirect tests
- What the pricing scales with (number of visitors, number of tracked events, number of users, and so on)
- Whether you can view it together with the data you use to build hypotheses, such as heatmaps
The end of Google Optimize
Google Optimize, which was widely used as a free A/B testing tool, was discontinued in September 2023. Sites that had been using Google Optimize have had to move to other tools.
Today there are various options: dedicated A/B testing tools such as Optimizely, VWO, and AB Tasty; tools that combine heatmaps and A/B testing, such as the Japan-based Ptengine and SiTest; and experimentation platforms for developers. The features and budget you need vary greatly with the size of your site, so it is important to choose what fits your own use. For differences in pricing ranges and approaches among the major tools, see A/B Testing Tools Landscape 2026.
Keep Improving by Combining Heatmaps and On-Site Engagement
A/B testing delivers more when combined with other tools than when used alone.
The improvement flow is a repeating cycle of "find → create a fix → verify."
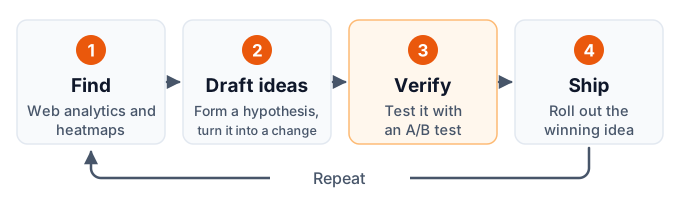
- Find: use web analytics to identify pages with problems, and heatmaps to pinpoint problem spots within the page
- Create a fix: form a hypothesis from the problem you found and create the change
- Verify: use an A/B test to check whether the change really improves results
- Apply and move on: apply the version that did better, and observe the changed page with a heatmap again
Looking at a heatmap after the A/B test results come in is also useful. When B wins, checking how visitor behavior changed (whether people read further down, whether the places they click shifted) gives you clues to "why it was better" and leads to the next hypothesis.
The A/B testing mindset also applies as is to on-site engagement measures, where instead of changing the page itself you show guidance in a popup or sticky bar. Whether you are comparing showing versus not showing, the wording, or the timing of display, the principle is the same: split visitors randomly and compare during the same period. The basics of on-site engagement are explained in What Is On-Site Engagement?.
About HeatMapX
HeatMapX is a tool that lets you measure heatmaps by adding a tag to your site, and you can start with the free Free plan (see the pricing page for plan details). The A/B testing feature is being rolled out in stages. Start by using heatmaps to understand how your own site is viewed, and having a hypothesis about where to experiment ready lets you move quickly when you start A/B testing.
If you want to compare heatmap tools with other products before choosing, see also Heatmap Tool Comparison.
A/B Testing FAQ
What is A/B testing, in simple terms?
It is a method where you randomly show visitors two versions of a page during the same period and compare which one performs better using numbers. Unlike comparing before and after a change, it lets you check the effect of a change separately from other factors such as seasons and ads.
How long should an A/B test run?
Estimate it by dividing the required sample size by the number of visitors per day. To avoid day-of-week bias, use multiples of 7 days; a common rule of thumb is to run for at least 1 to 2 weeks. Even if a high-traffic site reaches the required number in a few days, we recommend continuing for a week. Conversely, if the estimate is well over 2 months, revisit the design.
How much traffic do I need to run an A/B test?
There is no single standard. It depends on your current conversion rate and the size of the difference you want to detect. In the calculation example in this article, confirming a 20% relative improvement on a page with a 2.0% conversion rate required about 21,100 visitors per variation. If your traffic is low, you can reduce the required number by focusing on bigger changes or using an earlier-stage metric.
What should I do if there is no significant difference?
Avoid extending the test until it becomes significant after the planned period. Record that "this change did not show a difference of the size we wanted to detect," and look back at whether the hypothesis was wrong or the change was too small. If the results are the same either way, it is fine to choose whichever is easier to operate. No significant difference is not a failure; it is one kind of result.
If the p-value is below 0.05, can I say B is better?
No. A p-value is "the probability of seeing a difference at least as large as the one observed, by chance, if there were truly no difference," not "the probability that B is better." When judging at a 5% significance level, about 1 in 20 changes that have no effect will still show a significant difference. Also check the size of the difference, the confidence interval, and the guardrail metrics, and for important changes keep watching the numbers after applying them.
Does A/B testing hurt SEO?
Google publishes guidance saying the impact on search can be limited if you follow it. The four key points are: don't show crawlers and people different content, add rel="canonical" in tests on separate URLs, use 302 for redirects, and end the test and clean up the settings once the necessary period has passed. For details, see the "A/B Testing and SEO" section above.
Summary: Start with One Hypothesis
A/B testing is a method of randomly splitting visitors and comparing them during the same period, so that you can confirm the effect of a change separately from other factors. Here are the key points of this article.
- How it works: assign visitors at random, serve both versions during the same period, and keep showing the same person the same version. This narrows the cause of any difference to "what you changed"
- How to proceed: 6 steps of goal and metric → hypothesis → create the variation → run → judge → apply. Decide the metric, data volume, duration, and judging criteria before you run
- Data and duration: the smaller the difference you want to confirm, the more data you need. Use multiples of 7 days, at least 1 to 2 weeks
- Significance: a guideline for whether a difference is hard to explain by chance. A p-value is not "the probability that B is winning," and "not significant" does not mean "there is no difference"
- Avoiding mistakes: don't stop on interim results, limit changes to what one hypothesis covers, and use one primary metric
- When traffic is low: focus on big changes, high-traffic pages, and earlier-stage metrics, and fill the gaps with observation and interviews if that isn't enough
As a next step, we recommend picking one page on your site that is closest to results and gets many visitors, and starting by checking that page's problems with data. Use heatmaps and web analytics to find "where there seems to be a problem," then write one hypothesis that spells out the four points: fact, problem, change, and metric. With one hypothesis in hand, you can estimate the required data and duration and design your first A/B test.
A single test won't necessarily change your numbers dramatically. But building up verified facts one at a time is the foundation for improving a site without relying on hunches.